Boyong Wu 吴博镛
Hello hello! :) I’m a graduating M.Sc. Computer Science student at the
Technical University of Munich. I work on multimodal
learning, computer vision and explainable AI, and my favourite part is putting the
research ideas into the pipeline that runs them.
I am a student researcher in the Explainable Machine
Learning group at Helmholtz Munich,
with Zeynep
Akata, where I am having an amazing time. My first paper was recently
accepted at ECCV 2026, where we analysed how multimodal large language models process
visual information throughout their layers: why and how LLM layers progressively recover
visual quality, and the influence of bidirectional attention on MLLMs. I’ve also
shipped software in industry, CI/CD for the Volkswagen Group In-Car App Store at
CARIAD, tried building a startup called
Squareflick, and assembly line engineering at
Audi.
Away from that I build things for the fun of it, rendering, diffusion, VR, and small web
tools for problems that annoy me.
I also like badminton, snowboarding and great food :)
Github
G. Scholar
LinkedIn
b.wu at tum dot de
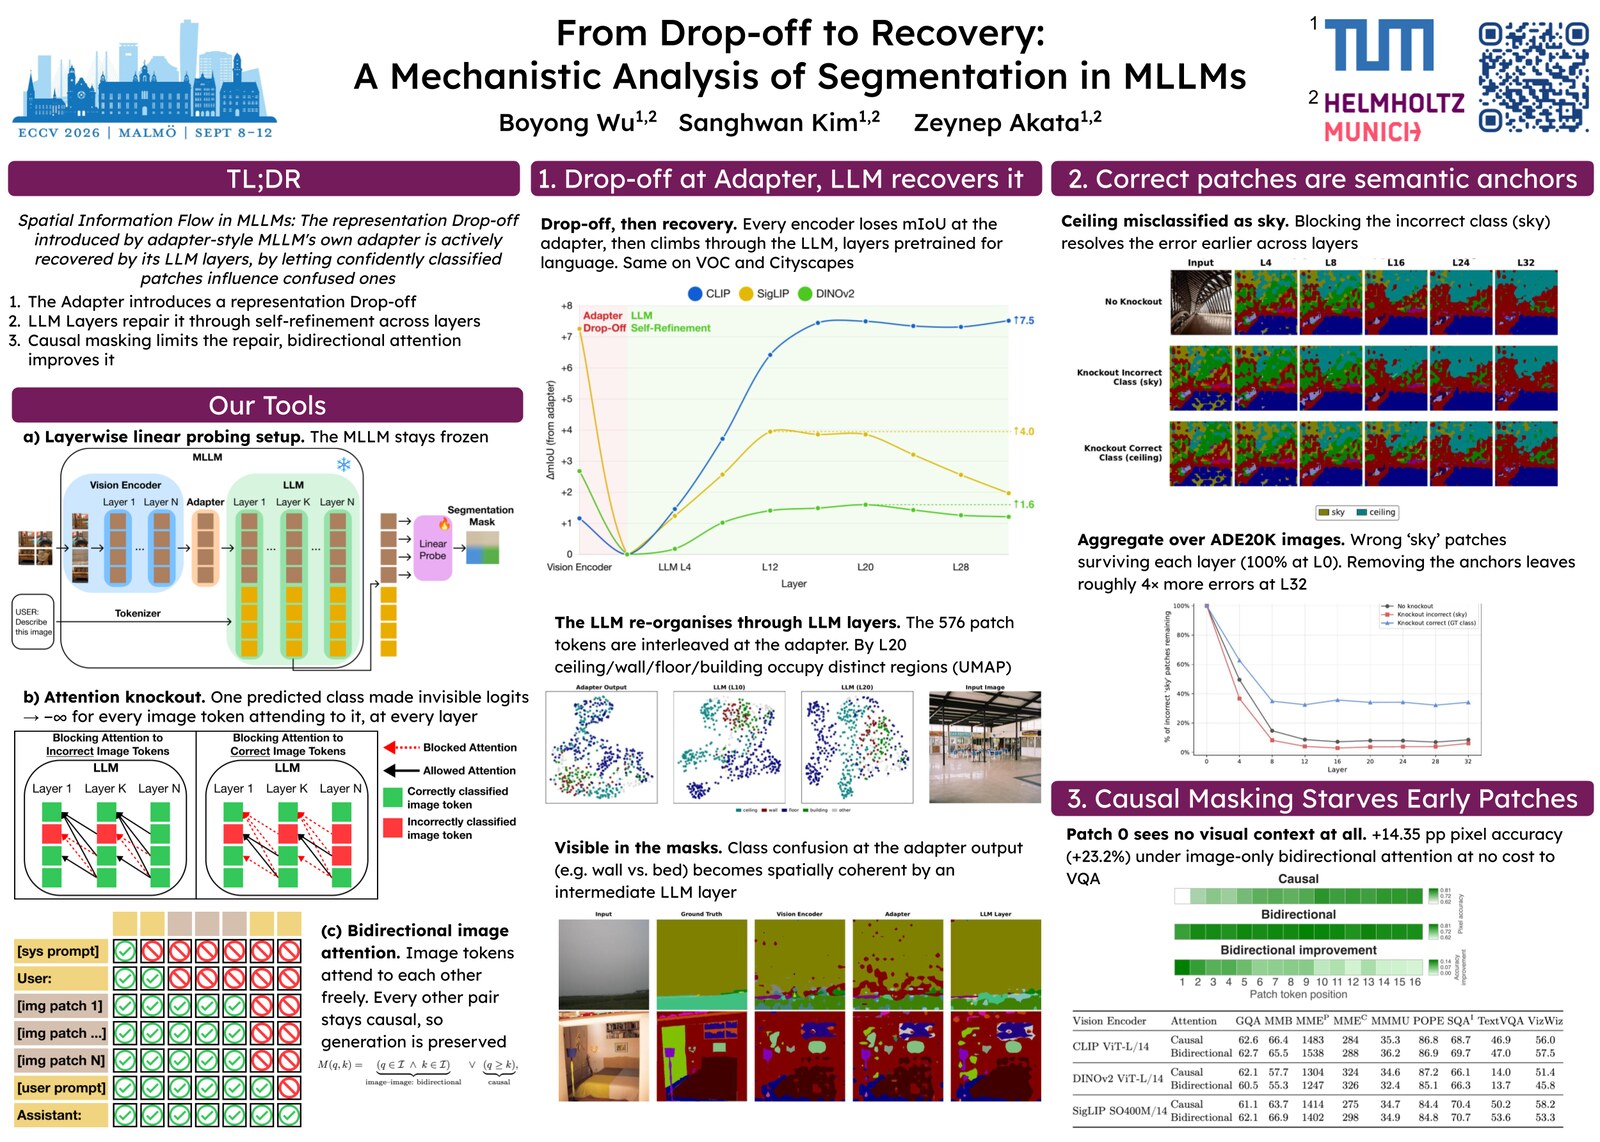
From Drop-off to Recovery: A Mechanistic Analysis of Segmentation in MLLMs
Boyong Wu, Sanghwan Kim, Zeynep Akata
European Conference on Computer Vision (ECCV) 2026
Springer •
arXiv •
Code (Coming Soon)
AI consultant in the AI and New Technologies team at Siemens AG.
Student researcher in the Explainable Machine Learning group at Helmholtz Munich, working with Sanghwan Kim and Zeynep Akata on multimodal learning, segmentation and explainable AI.
Software engineer at CARIAD SE, on the In-Car App Store for the Volkswagen Group. Designed and implemented the CI/CD pipelines for the app store repository, and automated sprint governance and reporting pipelines using REST APIs.
Industrial engineering intern at Audi AG, on assembly for the A6 and A7. Devised a plan to reduce assembly time by 40% at one station by evaluating assembly steps and part variance.
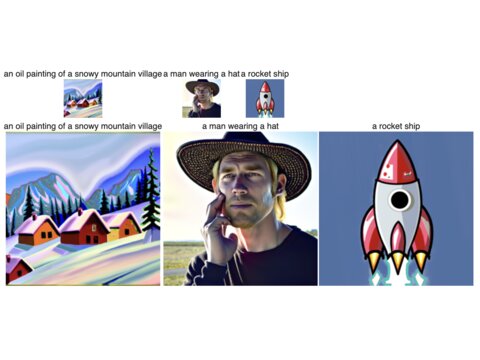
How does text to image diffusion work?
Sampling loops, classifier-free guidance, inpainting and visual anagrams on a pretrained model,
then a denoising U-Net trained from scratch to show where the pictures actually come from.
Code
Tower Wizard
A hand-tracked VR game for the Meta Quest: stand on a tower, cast spells with your bare hands
and hold off waves of monsters until the timer runs out. Built in Unity 6 with the Meta XR SDK.
Built with a team of four
Code
Morph my Face into Taylor Swift!
Hand-labelled correspondences, Delaunay triangulation and affine warps that walk one face into
another, then average a population into a mean face and push past it into caricature.
Code
NeRF explained
Fitting a neural field to a single image first, then a full neural radiance field from multi-view
photographs, with volume rendering and novel views.
Code
How does the panorama feature on our phones work?
Homographies and rectification by hand, then the automatic version: Harris corners, adaptive
non-maximal suppression, feature descriptors, matching and RANSAC.
Code
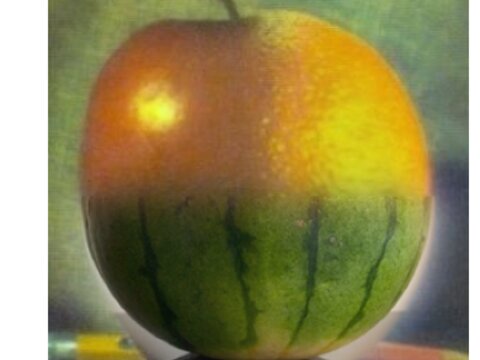
This is how we morph 2 single photos into a one seamlessly
Finite difference and derivative-of-Gaussian filters, image sharpening, hybrid images, and
multiresolution blending with Gaussian and Laplacian stacks.
Code
Squareflick
Use the Kanban principle with QR codes to keep track of your consumable materials.
Squareflick Time
Remember the classic hourly chime on Casio watches? You can have that again, in a browser tab.
restock.link
My private ChatGPT.